A Familiar OSPF Failure
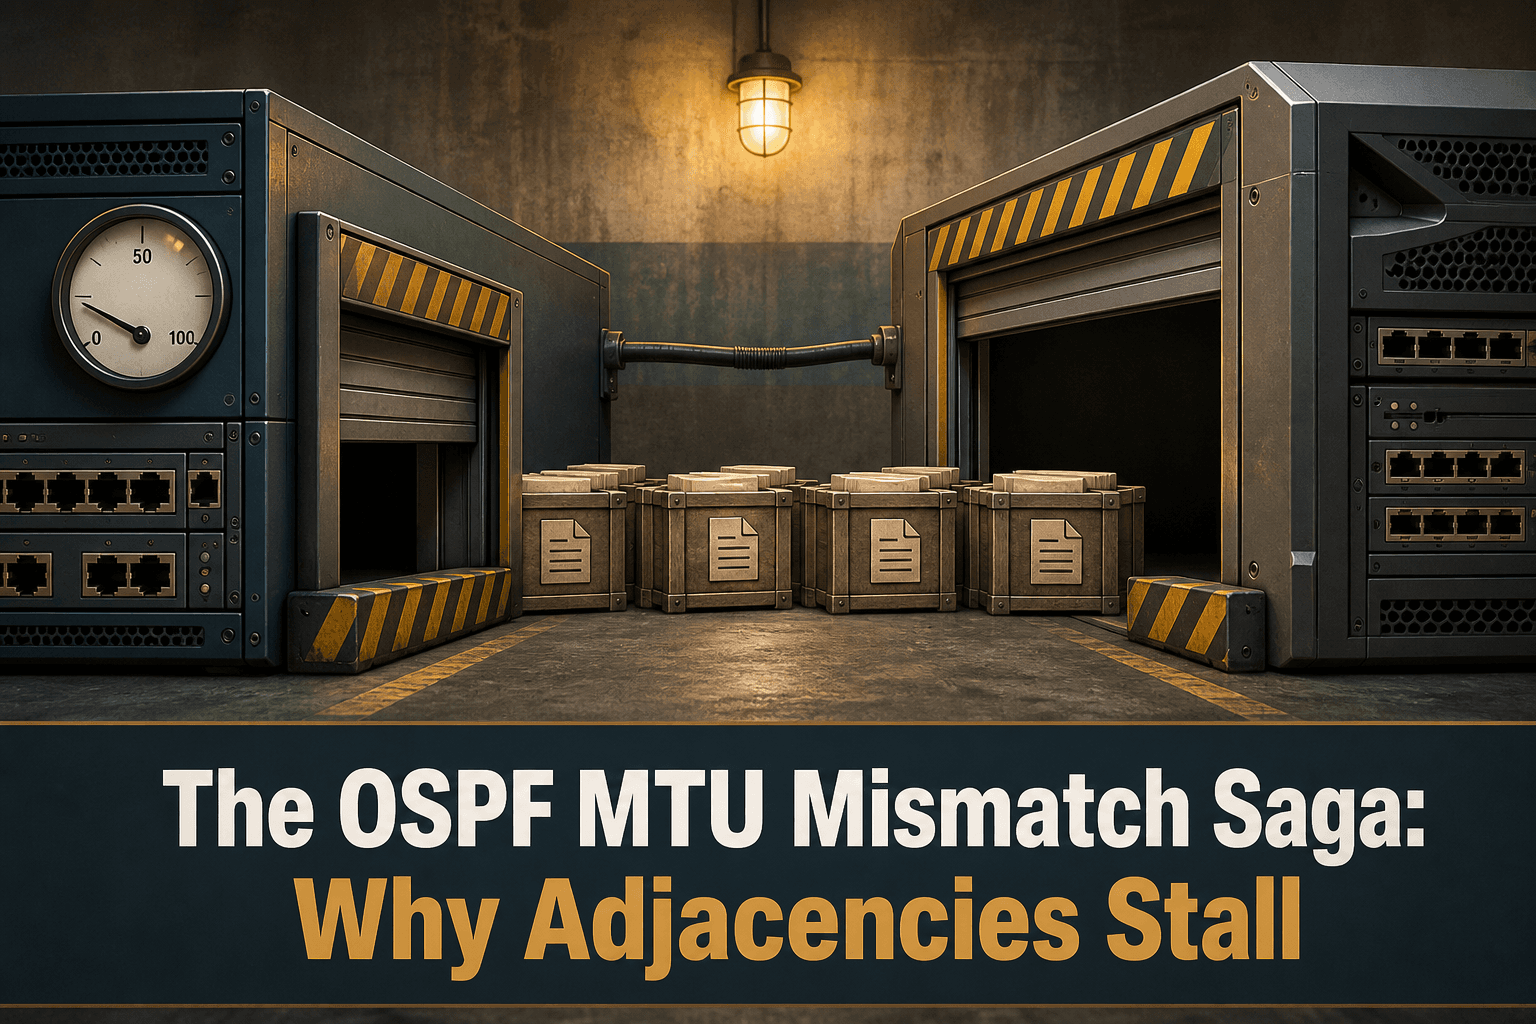
An OSPF adjacency that becomes stuck during database exchange is a symptom familiar to many network engineers. A common cause is an MTU mismatch between adjacent OSPF routers: the devices can discover one another, but they cannot complete the exchange needed to establish a fully functioning adjacency.
That distinction matters operationally. Basic connectivity or successful neighbor discovery does not prove that the complete OSPF adjacency process will succeed.
The source article also explores a particularly unusual edge case: an interface declaring its MTU as zero. This behavior turns a seemingly straightforward mismatch into a deeper implementation question, especially when equipment from different vendors is involved.
Why MTU Consistency Matters
The maximum transmission unit defines the packet size an interface is expected to handle. When adjacent OSPF interfaces disagree about that value, database exchange can stall rather than progress normally.
From an engineer’s perspective, the resulting pattern is deceptive:
The physical or logical link may appear operational.
The routers may recognize each other as OSPF neighbors.
The adjacency does not finish forming.
The failure points toward the database exchange phase rather than simple reachability.
This is why MTU validation should be an early troubleshooting step whenever an OSPF relationship remains stuck at this stage.
The Multivendor Complication
In a multivendor network, matching the intended MTU is not always as simple as comparing two commands. Vendors can expose interface settings differently, and unusual declared values may trigger implementation-specific behavior.
The zero-MTU case highlighted by the source is a useful warning: do not assume that an unexpected value is interpreted identically on every platform. Engineers should verify the effective configuration and observed adjacency behavior on both ends of the link rather than relying on familiar syntax from a single vendor.
A disciplined investigation should answer three questions:
What MTU is configured or declared on each adjacent interface?
Are both routers using values that are mutually compatible during OSPF database exchange?
Does either platform apply special behavior to an unusual value such as zero?
A Practical Detection Workflow
When an adjacency stalls during database exchange, use a structured process instead of repeatedly resetting the routing protocol:
Identify both endpoints. Confirm the exact interfaces participating in the OSPF relationship.
Collect both configurations. Retrieve the current interface and OSPF configuration from each router.
Compare MTU-related settings. Look for explicit values, inherited settings, or unusual declarations.
Account for vendor differences. Do not expect equivalent behavior merely because the commands look similar—or different behavior merely because the syntax differs.
Correct the inconsistency. Align the interface configuration according to the intended network design and supported platform behavior.
Verify adjacency formation. Confirm that OSPF proceeds beyond database exchange after the change.
Preserve the evidence. Record the previous and corrected configurations so the root cause remains auditable.
An adjacency reset may reproduce the symptom, but it does not remove the underlying configuration mismatch.
Remediation Without Creating a New Problem
An MTU change can affect more than OSPF. Before modifying production interfaces, engineers should understand the intended link design and review both endpoints. The goal is not simply to make the warning disappear; it is to establish a consistent, supportable configuration.
For repeatable remediation:
Define the expected MTU for each link type.
Validate both ends before applying a change.
Use controlled configuration updates rather than ad hoc edits.
Confirm OSPF behavior after remediation.
Retain a known-good configuration for rollback.
Check similar links for the same drift pattern.
The last point is particularly important in larger environments. A mismatch found on one adjacency may indicate inconsistent templates or configuration drift elsewhere.
How ConnectMyAssets Helps
ConnectMyAssets provides an on-prem, vendor-agnostic way to manage this problem across heterogeneous infrastructure.
Dynamic CMDB and Topology: identify the routers and interfaces associated with affected links.
Backup & History: compare configuration versions, find when an MTU-related setting changed, and retain a known-good version for one-click rollback.
Compliance Engine: define checks for expected interface standards and flag configuration drift across vendors.
Automation: apply reviewed, repeatable corrections to multiple affected devices instead of editing each router manually.
AI Insights (local): analyze infrastructure information locally to help surface configuration inconsistencies without sending operational data to a cloud service.
ConnectMyAssets does not replace protocol-level troubleshooting. It gives engineers the configuration history, asset context, topology, and automation needed to turn a one-off OSPF incident into a traceable and preventable operational issue.
The Operational Lesson
The classic “OSPF stuck during database exchange” symptom still deserves a basic MTU check. However, the zero-MTU investigation shows why engineers should avoid treating the issue as a purely academic certification scenario.
In real multivendor networks, the effective behavior of each implementation matters. Compare both endpoints, validate what each router is actually declaring, remediate the configuration consistently, and preserve the change history for the next incident.
Source: ipSpace.net