A Public Resource on Network Reliability
ipSpace.net has made Rachel Traylor’s five-hour webinar, Reliability Theory: Networking through a Systems Analysis Lens, available without a valid ipSpace.net account. The announcement also points readers toward the publisher’s other free videos and webinar roadmaps.
The short announcement does not provide a detailed syllabus. Rather than presenting the following points as a summary of the webinar, this article uses its systems analysis lens as a starting point for practical questions that network teams can apply to design and operations.
Start With the Service, Not the Device
A device can be reachable while the service that depends on it is impaired. Conversely, a failed component might not affect users if the system has a working alternative path.
Reliability analysis should therefore begin by defining what must remain available:
Which user or machine-to-machine service is being protected?
Which network, security, addressing, authentication, power, and upstream dependencies support it?
What constitutes degradation rather than total failure?
How will operators detect that condition?
What must be restored first?
This shifts the conversation from isolated equipment health to end-to-end service behavior.
Map Dependencies Before Adding Redundancy
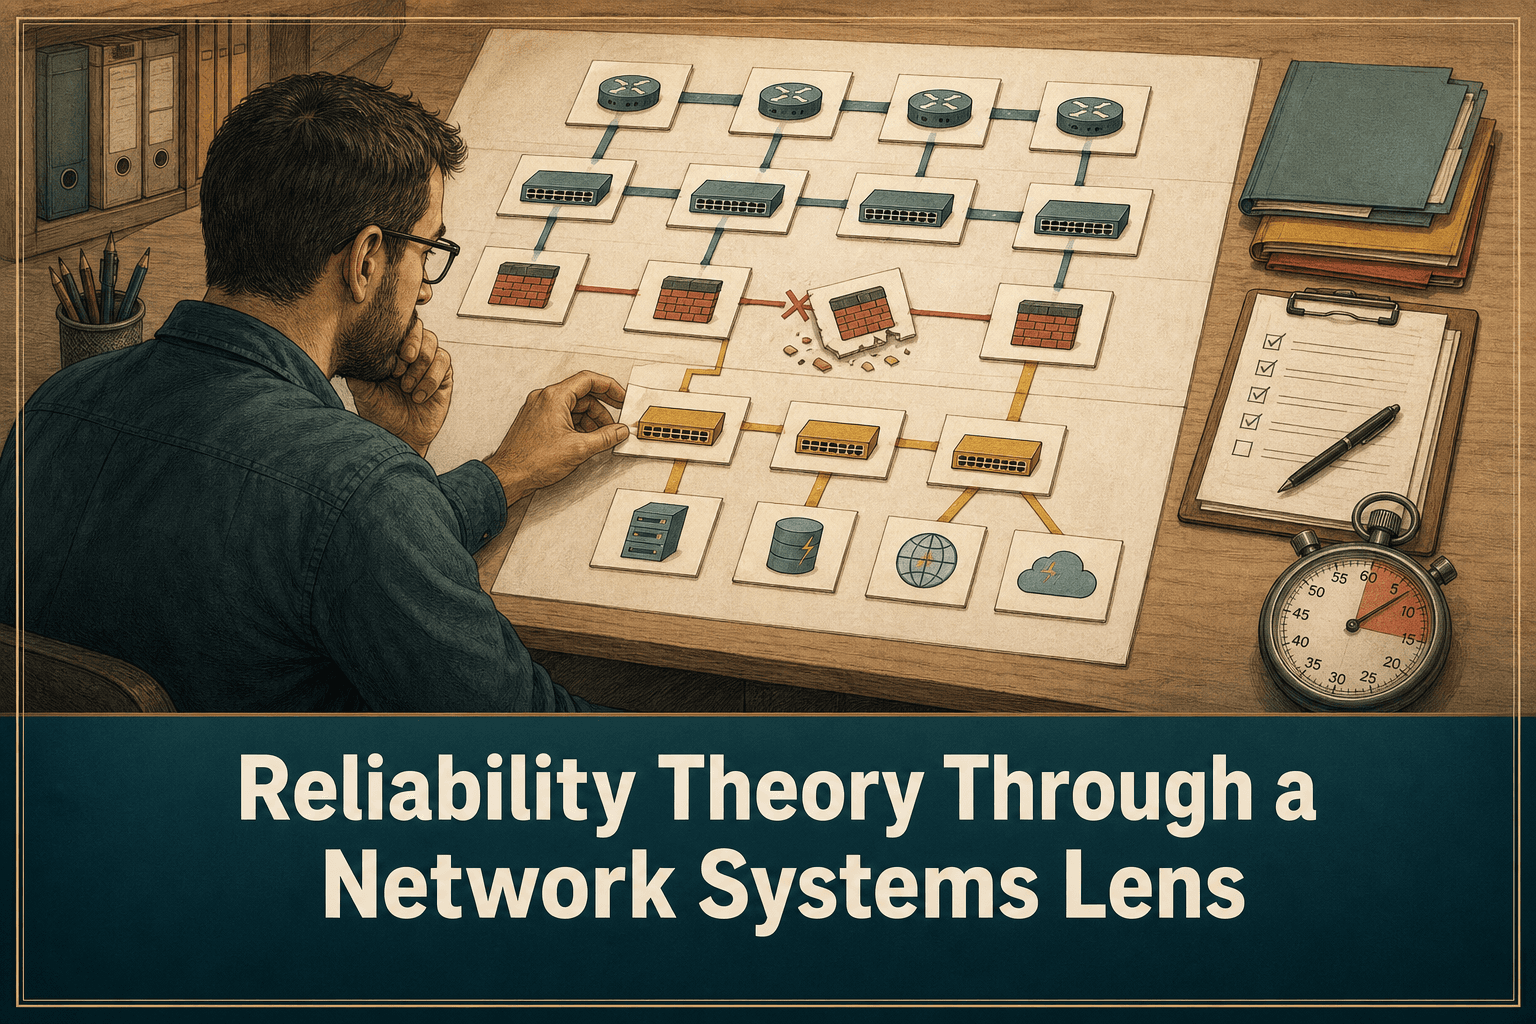
Redundancy is useful only when alternate components do not inherit the same critical dependency. Two paths may still share a firewall, power source, physical conduit, credential, configuration error, or operational procedure.
A practical systems-analysis exercise is to trace each important service through its dependencies:
Identify the service entry and exit points.
List the devices and logical functions traversed.
Record shared infrastructure and administrative dependencies.
Mark where failures can be isolated.
Verify whether the intended alternate path can actually carry the service.
A current topology and asset inventory make this exercise repeatable instead of dependent on institutional memory.
Treat Configuration State as Part of Reliability
Network reliability is not solely a hardware-design problem. Configuration state affects routing, segmentation, access control, addressing, and recovery.
Operational questions include:
Is there a known-good configuration for each critical asset?
Can the team identify exactly what changed before an incident?
Are backups recent, complete, and recoverable?
Is rollback an established procedure rather than an improvised response?
Can configuration drift be detected across multiple vendors?
A backup that cannot be found, compared, or restored quickly provides limited operational value. Version history and tested recovery procedures turn configuration data into a resilience capability.
Analyze Failure and Recovery Together
Failure prevention is only one side of reliability. Teams should also examine what happens after a fault is detected.
For each important scenario, ask:
What evidence exposes the failure?
Who owns the response?
Which access path remains available during the incident?
Are credentials and device records accessible on premises?
Which configuration or automation action is safe to execute?
How is restoration validated from the service perspective?
This approach links architecture to runbooks, access controls, backups, and operational responsibilities. It also reveals situations in which the recovery mechanism depends on the system that has failed.
Use Change as a Reliability Test
Planned change is an opportunity to verify assumptions about the system. Before implementation, teams can document the expected service impact, dependencies, validation checks, and rollback conditions. Afterward, they can compare the intended state with the observed state.
A disciplined workflow includes:
Capture the pre-change configuration.
Confirm affected assets and dependencies.
Define measurable success and rollback criteria.
Apply the smallest controlled change possible.
Validate the service, not just device reachability.
Preserve the resulting configuration and audit evidence.
Automation can improve consistency, but it should operate from reviewed inputs and include clear failure handling. Automating an incorrect assumption merely applies it faster and more broadly.
Include Lifecycle, Vulnerability, and Compliance Context
Systems analysis also benefits from information beyond topology. An asset approaching end of support, carrying a known vulnerability, or drifting from an approved baseline may alter the risk of an otherwise sound design.
These factors should be evaluated in context:
Lifecycle: Can the component still receive vendor support or required updates?
Vulnerability exposure: Which assets are affected, and what services depend on them?
Compliance: Does the current configuration satisfy the organization’s required controls?
Recoverability: Are configuration history, credentials, and procedures available when needed?
None of these data points alone measures reliability. Together, however, they help teams identify dependencies and operational constraints that a diagram may omit.
How ConnectMyAssets Helps
ConnectMyAssets provides an on-premises foundation for turning systems-analysis questions into maintained operational evidence across multi-vendor infrastructure.
Dynamic CMDB maintains asset and dependency context for reliability reviews.
Topology helps teams inspect paths and shared infrastructure before changes or incident exercises.
Backup & History provides configuration versioning, change comparison, and one-click rollback.
Automation & ZTP supports repeatable, controlled configuration workflows.
Credential Vault and SSH Bastion help preserve governed administrative access during operations and recovery.
Per-asset CVE Tracking connects vulnerability information to the equipment concerned.
End-of-Life Tracking highlights lifecycle conditions that can constrain maintenance and recovery plans.
Compliance Engine evaluates infrastructure against frameworks such as NIS2, ISO 27001, PCI, CISA, and NIST requirements.
These modules do not prove that a network is reliable. They provide the inventory, history, access, lifecycle data, and configuration evidence needed to analyze reliability assumptions and act on the findings.
A Practical Next Step
Use the public webinar as a prompt for a focused review of one critical service. Map its dependencies, identify shared failure points, confirm configuration recovery, and test whether operational records are sufficient for restoration. A small, evidence-based exercise can expose assumptions that broad claims of “redundancy” often leave untested.
Source: ipSpace.net