A Systems View of Network Reliability
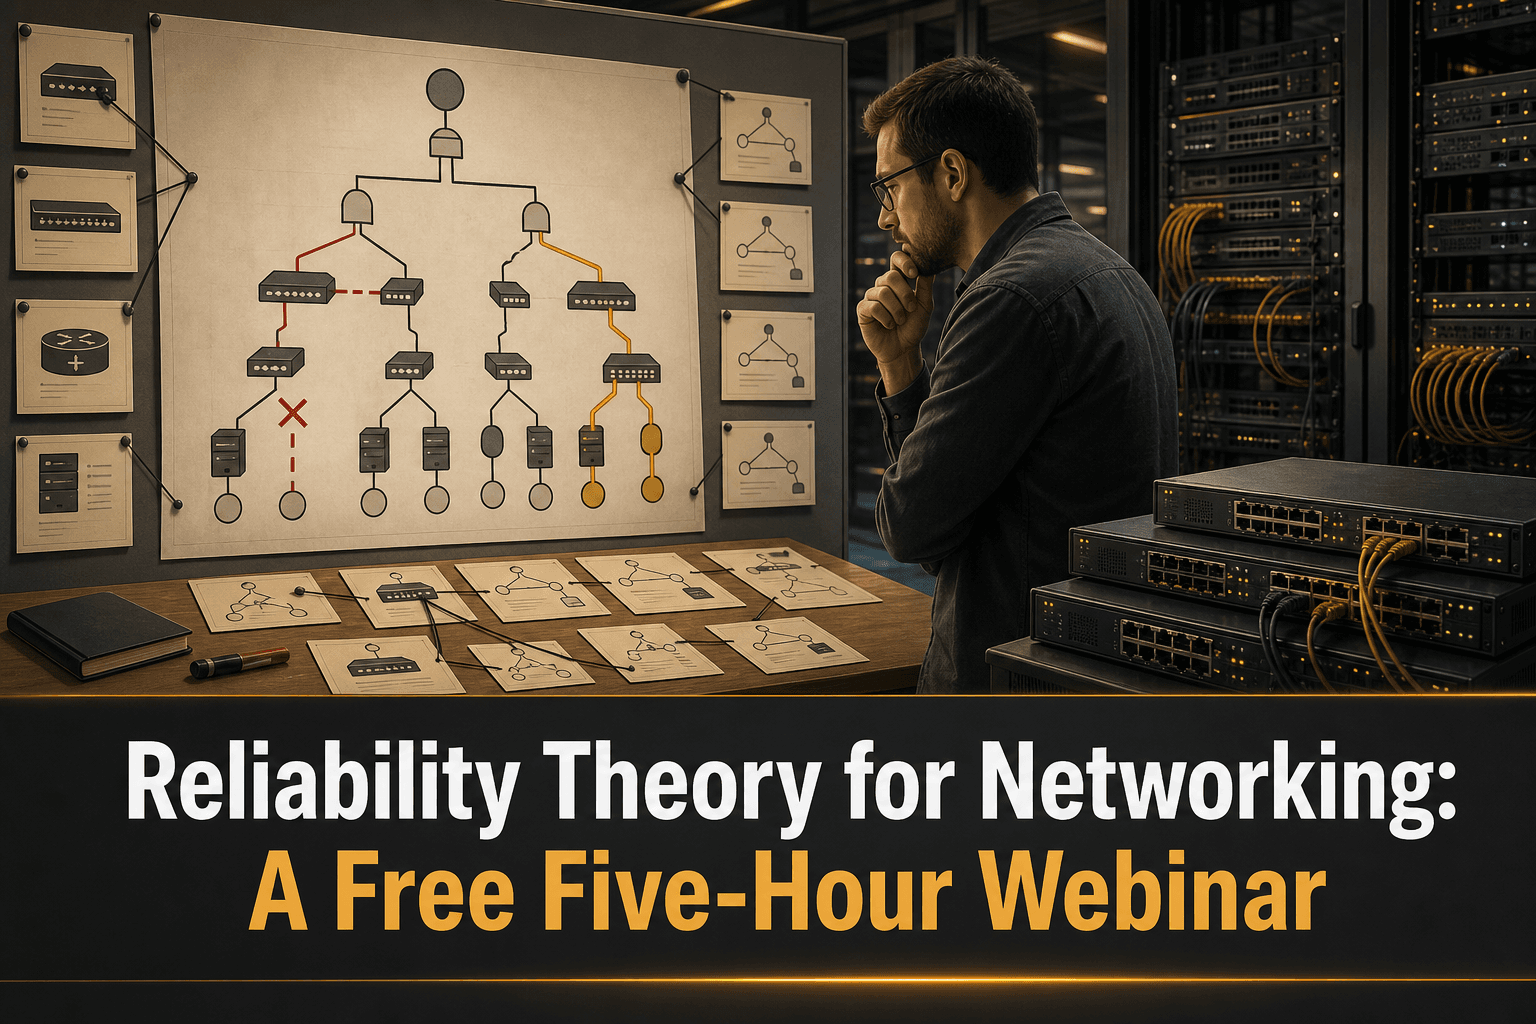
ipSpace.net has made Rachel Traylor’s five-hour webinar, Reliability Theory: Networking through a Systems Analysis Lens, available without requiring a valid ipSpace.net account.
The announcement is brief and does not provide a detailed syllabus. Its premise is nevertheless important for network teams: reliability should be considered at the level of the complete system, not only at the level of individual routers, switches, firewalls or links.
A component can be healthy while the service that depends on it is unavailable. Conversely, a component can fail without interrupting the service if the wider system handles that failure as intended.
The public webinar provides an opportunity to explore that distinction through a systems-analysis lens. ipSpace.net also points visitors toward its broader collection of free videos and the free-content option available from webinar roadmaps.
Turning the Reliability Lens into Operational Practice
A systems perspective can change the questions asked during network design, failure analysis and troubleshooting. Instead of stopping at “Which device failed?”, teams can examine how dependencies and operational processes combined to produce an outcome.
A practical review can follow five steps:
Define the service boundary. Identify the users, applications, network segments and external dependencies involved.
Map the dependency chain. Examine the paths, devices, policies, addressing and supporting services required for the service to operate.
Separate symptoms from causes. A failed reachability test or interface alarm indicates an observable condition, not necessarily the originating fault.
Compare current state with known history. Configuration changes and asset history can help establish what changed before an incident.
Convert findings into controls. Update configurations, procedures, automation and compliance checks so that the same condition is easier to detect or avoid.
Applying the Approach to Network Design
Reliability is not synonymous with adding a second device or link. A design review should also look for shared dependencies that could affect multiple paths, as well as the operational steps required to restore service.
Useful questions include:
Which services depend on this network path or policy?
Do apparently redundant paths share an upstream dependency?
What configuration state would be needed during recovery?
Can operators identify the last known-good configuration?
Are recovery actions documented, controlled and repeatable?
Does the asset inventory reflect the infrastructure currently in production?
These questions connect architecture with operations. A resilient diagram is valuable, but teams also need accurate state information and a recoverable configuration history when an incident occurs.
Improving Failure Analysis and Troubleshooting
Systems-oriented troubleshooting favors evidence over isolated assumptions. Teams can begin with the affected service, move through its dependencies and compare observations against configuration and topology history.
This approach can help structure incident work around:
Scope: what is affected and what remains operational.
Sequence: which event or change occurred first.
Dependencies: which shared services or paths are involved.
State: whether configurations, policies or inventory changed.
Recovery: which controlled action can restore the expected state.
The goal is not merely to replace a failed component. It is to understand why the system produced the observed impact and what operational evidence is needed for a safer recovery.
How ConnectMyAssets Helps
ConnectMyAssets provides an on-prem, vendor-agnostic foundation for applying this reliability mindset across multi-vendor infrastructure.
Dynamic CMDB and Topology help teams maintain an operational view of assets and their relationships.
Backup & History preserves configuration versions, supports change comparison and provides one-click rollback to a selected configuration.
Compliance Engine turns required configuration conditions into repeatable checks aligned with frameworks such as NIS2, ISO 27001, PCI, CISA and NIST.
Automation & ZTP helps standardize approved operational actions instead of relying on inconsistent manual execution.
End-of-Life tracking and per-asset CVE Tracking add lifecycle and vulnerability context to infrastructure reviews.
Credential Vault and SSH Bastion support controlled administrative access during routine work and incident response.
ConnectMyAssets does not replace a reliability model. It supplies the inventory, configuration history, topology, controls and automation needed to put systems-level analysis into day-to-day network operations.
Source: ipSpace.net